

What if quantum computing could help businesses design more profitable rebate programs? Using NVIDIA CUDA-Q, Tom Chiles, Director of Product and Technology – Innovation at Vendavo, explores how quantum algorithms could account for customer behavior, interconnected demand, and financial risk to optimize rebate strategies. The result is a compelling look at how emerging computational approaches could eventually turn some of B2B pricing’s most complex challenges into commercial advantage.
I was recently part of a very lucky cohort of postgraduate students to attend an NVIDIA quantum acceleration day organized at the University of Manchester ran by the brilliant Esperanza Cuenca-Gómez (Developer Relations Manager for Quantum Computing at NVIDIA). It was a full day introduction to the wonderful and confusing world of quantum computing, with hands on coding sessions using the NVIDIA CUDA-Q platform.
It immediately got me thinking on the potential applications in the space of B2B pricing management and optimization. I have dived into the very funky world of quantum algorithms with the NVIDIA platform to see if an approach using this emerging technology could be applied to rebate program construction.
Each of the technical sections has a corresponding python notebook section using the CUDA-Q platform, and if you have solid local hardware, you can run it locally. The public repository is available here, to access the python notebook.
Rebate program mathematics 101
There are many (many) different types of rebates, but for simplicity I’m going to focus throughout on one of the most common: retroactive volume tier rebates. These are off-invoice incentives aimed at driving future purchases and loyalty to the brand.
The retroactive nature means that if a customer reaches a tier, all eligible previous purchases (in most cases of the same product) are also discounted. This means potential big savings if a product is continually purchased in bulk to get over the “cliff edge” to achieve the next rebate tier.
The overall revenue for a customer purchasing a product repeatedly throughout the year is calculated as:
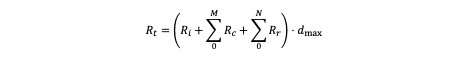
Where Rt is the total revenue throughout the year of continually purchasing the same product, Ri is the initial revenue on the first purchase, Rc is the revenue for number of purchases M not yet reached a rebate threshold, and Rr is the revenue for number of purchases N taking the customer over a rebate threshold and dmax is 1 minus the maximum retroactive discount achieved throughout the year.
Rebate tiers can be constructed in a simple format, an example program structure for a product is:
| Tier | Annual volume (units) | Rebate rate |
| Tier 1 | 0 to 9,999 | 0% |
| Tier 2 | 10,000 to 24,999 | 2% |
| Tier 3 | 25,000 and above | 4% |
Take a single product at a list price of £50 a unit. The retroactive structure creates a discontinuity at every threshold, and the one at Tier 3 is worth looking at closely:
| Annual units | Spend | Rate | Rebate | Net revenue |
| 24,999 | £1,249,950 | 2% | £24,999 | £1,224,951 |
| 25,000 | £1,250,000 | 4% | £50,000 | £1,200,000 |
Selling one more unit raises the rebate by around £25,000 and reduces the supplier’s net revenue by £24,951. The size of the cliff at any threshold is:

The cliff has two sides. For the customer it is a powerful incentive to push volume over the line, which is exactly the behavior the program is built to create. For the supplier it is margin risk, because a threshold placed where a customer would have landed anyway pays the higher rate on the whole year for no change in behavior at all.
The art of constructing these rebate tiers, is to try and incentivize purchasing as much volume as possible, but not over discounting the reward, resulting in a large retroactive “true up” reducing the revenue of your business unnecessarily and creating margin leakage. The big benefit of rebates over upfront discounting on the purchase, is the customer is driven to loyalty to the brand and must hit a big milestone (e.g. volume threshold) before unlocking big discounts.
Quantum computing 101
I should preface this bit by saying I am so not an expert in quantum computing and I was definitely not top of my class in physics. I will do my best to provide a brief overview of the fundamental concepts needed to grasp to then understand the theoretical approach proposed in the sections below for a quantum rebate program.
Qubits, interference, entanglement, and superposition
Classical computing is based foundationally on the concept of a binary bit that is either 0 or 1, with every coding language an abstraction above this. A qubit in quantum computing can be 0 (written as |0⟩, 1 (written as (written as |1⟩) or in spooky superposition, a blend of both states. This blend can be described using the equation:
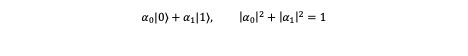
Where α are referred to as amplitudes, and the squared magnitudes of the amplitudes must sum to 1. The squared magnitude of each amplitude gives the probability of that outcome when the qubit is directly measured. Measuring always gives a binary 0 or 1 outcome and the superposition is gone (the quantum wave function collapses when measured to provide a definitive answer, think Schrodinger’s Cat!). The entire core concept behind quantum computing is to manipulate the qubits to maximize the outcome you are looking for, before measuring it.
Things get stranger with two qubits, this is where the potential superiority of quantum computing for highly complex, and high dimensional algorithms become evident. For two qubits there are now four basis states:
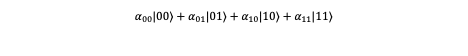
Every extra qubit as you can see, doubles the number of states, and as with one qubit the squared magnitudes of the amplitudes must sum to 1. Two classical computing bits sit in one of four states at a time (00, 01, 10, 11) whereas two qubits carry a value for all four at once, and the values can cancel each other out, which ordinary classical computing probabilities can’t. Amplitudes can reinforce or cancel one another. This is interference, and arranging quantum gates (we’ll get onto that soon) so that wrong answers cancel while right answers reinforce is where the speed up comes from.
Quantum gates, entanglement, and circuits
No not something from Star Wars, quantum gates perform a mathematical operation on a qubit to change its state, and a quantum circuit is a combination of these.
I’m going to go through the example of how to create entanglement from scratch, and get qubits into what is called a “Bell state”. You can see the diagram of the quantum circuit below, each horizontal line is a qubit:

This circuit takes two qubits and entangles them together by applying two different quantum gates, a Hadamard gate (represented as H), and a CNOT gate (drawn as a filled dot on the control wire joined to a ⊕ on the target wire).
The Hadamard gate starts by putting the control qubit (q0) in in an equal blend of 0 and 1 likelihood (imagine a coin remaining flipping in the air), putting it into superposition. The CNOT (controlled-NOT) gate acts on both qubits, applying the specific logic: if the control q0 is 1, flip the target q1; if the control is 0, leave it alone.
If you like matrix mathematics (and coming from an applied engineering background, I do!), the mathematical operations are:
1. The gate starts with four basis states corresponding to two qubits (the diagram example shows |00⟩):
|00⟩ = q0 is 0, q1 is 0 = (1, 0, 0, 0)T
|01⟩ = q0 is 0, q1 is 1 = (0, 1, 0, 0)T
|10⟩ = q0 is 1, q1 is 0 = (0, 0, 1, 0)T
|11⟩ = q0 is 1, q1 is 1 = (0, 0, 0, 1)T
Two qubits have four possible joint configurations. Each is written |q0 q1⟩ left character is the value of q0, right character the value of q1 and each is assigned one component of a four-element column vector:
With the full matrix of basis states for the two qubits:

2. Apply the Hadamard gate  to q0, which is in state
 , and apply nothing yet to q1 (so an identity matrix of
 is applied to q1 in the first step, the matrix version of multiplying by 1 as it can’t be empty). The tensor product of H ⊗ I is applied:


You can see that q0 is now in superposition by looking at the impact on each of it’s base states:

q1 reads 0 in both terms, so q1 is still definitely 0; q0 reads 0 in one term and 1 in the other with equal amplitude, so q0 is in superposition.

Here q1 reads 1 in both terms and q0 is again split across 0 and 1.
3. Apply the CNOT gate.
Now that q0 is successfully in superposition, the CNOT gate (I keep finding myself saying snot) is then applied across both qubits, with q0 as the control and q1 as the target. This is to apply the logic that where the control qubit is 1, the target qubit q1 is flipped, and where it is 0, q1 is left alone. Because q0 is in superposition rather than settled on a value, the gate does both at once. Both branches survive, each carrying its own pairing of q0 and q1. This means that q1 no longer has a state of its own at all. Neither qubit can be described independently of the other. The two qubits are entangled, one cannot be described without the other, and measuring one qubit tells you the result of the other:


4. Observe the result.

The only surviving terms are q0 = 0 paired with q1 = 0, and q0 = 1 paired with q1 = 1. Neither qubit reads a definite value on its own, but the two always agree. This is the Bell state, and it is what entanglement looks like written out.

Starting from |01⟩ the two qubits always disagree instead of always agreeing. Still entangled, still unreadable one qubit at a time.
Bernoulli variables
1. Introduction
The entire idea behind a quantum algorithm is to construct a series of gates to maximize the probability of the answer we want, before measuring it to actual see the result.
A Bernoulli random variable is the simplest thing to encode in a qubit, so it is a good place to start. It is the simplest random quantity: yes/no outcome. It must equal 1 with a probability of p and otherwise it is 0, i.e. a biased coin flip, with a fair coin being the special case where p = 0.5.

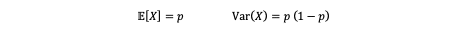
2. Load a Bernoulli variable into a qubit
A single qubit holds exactly the structure a Bernoulli variable needs. Put p straight into the amplitudes:
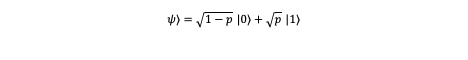
Measuring this qubit returns 1 with probability |√p|² = p, and 0 with probability 1 − p. That is the Bernoulli variable, by definition. The condition p + (1 − p) = 1 is doing the same job here that |α0|² + |α1|² = 1 did in the qubit section.
To build that state from |0⟩, rotate it. The Ry gate turns a qubit about the y axis by an angle θ:

Matching the two expressions gives sin(θ/2) = √p, so the angle to rotate by is:
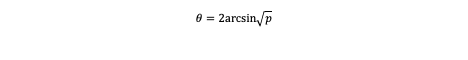
Take a coin biased to land heads three times in ten, p = 0.30:

Square the two amplitudes and you get 0.70 and 0.30, the coin’s two probabilities. One qubit, one gate, and the coin is loaded.
3. Measure it
Measure the qubit in the computational basis and it collapses to a single bit:
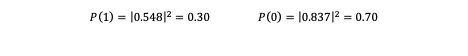
That is one flip of the coin, not the value of p. The superposition is gone, so taking a second sample means preparing the state again from scratch. Run the circuit N times, count the ones, and the estimate is:

Which improves with more shots, but slowly:
| Shots N | Typical error in p̂ |
| 100 | ± 4.6% |
| 1,000 | ± 1.4% |
| 10,000 | ± 0.46% |
The error shrinks like 1/√N, so ten times the accuracy costs a hundred times the shots. This is ordinary Monte Carlo sampling, and so far the quantum computer has done nothing a physical coin could not do more cheaply. Beating that 1/√N rate is what the next two sections are for.
One last thing before we scale up. Each customer can have their own qubit loaded with their own probability, so three customers give 2³ = 8 possible scenarios of who reaches the top tier, and a single measurement of all three samples one of them. That is the bridge to the rebate circuit later on: one qubit per customer, every combination held at once.
Grover operator
Named after Lov Grover, and probably the closest thing quantum computing has to a greatest hit. The Grover operator takes a state where the answer you want is sitting there with a small amplitude, and rotates that amplitude upwards, over and over, until the answer you want is the one you are overwhelmingly likely to measure.
It helps to rewrite a loaded qubit in terms of an angle, because the Grover operator is a rotation and rotations are easier to follow in degrees than in square roots:

Worth noticing that θp is exactly half the Ry angle we rotated by to load the probability in the first place.
The operator itself, usually written Q, is built out of two reflections:
- Flip the sign of the answer you are looking for, for us the |1⟩ state. On a single qubit that is just the Z gate.
- Flip the sign of everything except the starting state, sandwiched between the loading gate and its inverse.
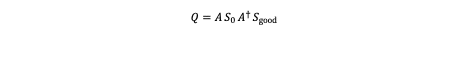
The useful bit is not how Q is assembled but what it does. Every single time you apply it, it rotates the state by a further 2θp:

Which means the probability of measuring a 1 after k applications is sin²((2k+1)θp). Take a customer with a 10% chance of reaching the top tier, so θp = arcsin(√0.1) ≈ 18.4° and each step rotates the state by about 36.9°:
| Steps k | Angle (2k+1)θp | P(good) |
| k = 0 | 18.4° | 10.0% |
| k = 1 | 55.3° | 67.6% |
| k = 2 | 92.2° | 99.9% |
| k = 3 | 129.0° | 60.3% |
| k = 4 | 165.9° | 5.9% |
After two steps, a 10% outcome has become almost certain. That is the whole trick: the amplitude of the answer we wanted was quietly rotated up, and the amplitude of everything else was rotated down to almost nothing, all before we measured anything.
Two things worth flagging before we move on. Keep applying Q past the point you need and the rotation carries straight on round, which is why k = 3 and k = 4 fall away again. And this is amplification, not estimation. We have made our preferred answer nearly certain, which is a different job to working out how likely it was to begin with.
That difference gives the same operator two quite separate uses:
| Use | What it does | Rebate question it answers |
| Grover search | Apply Q until the good outcome is nearly certain, about π/(4√p) steps, then measure | Find a scenario or design that meets a condition |
| Amplitude estimation | Measure how fast Q rotates the state, then read off θp and so p | Estimate the probability of reaching a tier, or the expected rebate cost |
Quantum amplitude estimations
Here is where it gets useful for us, because in a rebate program we rarely want to force an outcome to happen. We want to know how likely it already is.
Amplitude estimation uses exactly the same Grover operator, but asks a different question of it. Rather than applying Q until the answer we want is certain, we take advantage of the fact that Q’s rotation angle is the thing we are trying to find. Rotate by 2θp each time, measure the angle, and you have p:
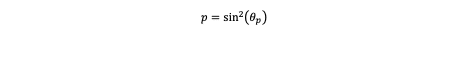
Simple sampling only ever looks at the state at k = 0, where the result barely depends on θp at all. Amplitude estimation measures it after many Grover steps as well, and there the angle has been multiplied by (2k+1), so even a tiny change in p produces a large and easily measured change in the result. To work out how fast a clock hand is turning you get a far better answer watching it for a hundred turns than for a fraction of one, and each Grover step is one more turn.
The version used here is maximum-likelihood amplitude estimation, which gets the same behavior out of the Grover operator alone and avoids the much deeper circuits that textbook phase estimation needs:
- Run in rounds, doubling the number of Grover steps each time: k = 0, 1, 2, 4, 8, 16, 32. Measure a fixed number of shots in each round.
- Count how many shots in each round gave the good outcome.
- Pick the value of θp that best explains every round at once.

Here hk is the number of hits after k steps and n is the number of shots per round. The early rounds give a rough answer with no ambiguity, and the later ones sharpen it.
The fair way to count the cost is the number of times the model circuit A runs, because in a real problem A is the expensive part. Classical sampling runs A once per sample. An amplitude estimation shot after k Grover steps runs A a total of 2k+1 times, because each step contains both A† and A.
At 100 shots per round, with rounds up to k = 32, that comes to 13,300 model runs. Given the same 13,300 runs, classical sampling reaches a typical error of about ±0.4%, while amplitude estimation reaches about ±0.05%. Up to 7x more accurate for the same effort, and the gap widens as the budget grows.
That is the quadratic speed up, and it is the entire reason this is worth doing. Two bits of small print though, and both matter. At small budgets there is no advantage at all: with only one or two rounds amplitude estimation is no better than sampling, and can be slightly worse. The benefit comes entirely from the large-k rounds, and those are also the deep circuits that real hardware struggles with. Everything here runs on a classical simulator, which gains nothing.
The potential benefit for rebate program construction
I appreciate the maths got slightly heavy toward the end of the previous section, but I want to make sure the foundational topics are covered at a high level before we construct a quantum algorithm for a B2B rebate program. Using the approaches above, we’re going to construct a quantum rebate algorithm that aims to maximize the number of important customers reaching the top tier of a rebate, whilst keeping below a rebate program budget amount for true-ups (a topic we introduced in the rebate section toward the top of this article). This is a constrained optimization rather than a single estimate, so the algorithm has two parts: amplitude estimation to score one candidate program, and a search over candidate programs on top of it. Similar approaches have been derived for credit risk analysis before (see here).
We are going to focus on the theory, what a circuit to try and solve this rebate problem might look like, the potential benefit, and corresponding python code using the Nvidia CUDA-Q platform. The workload is possible to run today because of GPU accelerated simulation using CUDA-Q, scaling beyond 15 qubits for state vector simulations is GPU territory and the Monte Carlo baseline also runs on GPUs.
Building a rebate program using quantum algorithms
1. The goal of the algorithm
Right, time to point the quantum computing theory at the rebates problem specifically, step by step.
The tension in a retroactive rebate program is easy to state and horrible to solve. You want as many of your valuable customers as possible to reach the top tier, because that is what drives the volume and the loyalty. But every customer who reaches it triggers a retroactive true-up, and if too many of them get there in the same year your rebate budget is gone. So there are two numbers to watch at once: a score we want to push up, and a risk we need to keep under a line.
Tiers 1 and 2 are fixed. The design choice is the top tier, and there are two options for the threshold and two for the rate, giving four candidate programs:
| Tier | Threshold | Retroactive rate |
| 1 | 2,000 units | 0.5% |
| 2 | 5,000 units | 1.5% |
| 3 | 8,000 or 12,000 units | 3% or 5% |
When a customer crosses the Tier 3 threshold, everything they have bought all year is re-rated from the Tier 2 rate up to the Tier 3 rate. That is the true-up, the cliff from the rebate section earlier:
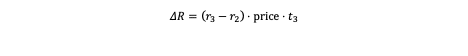
At a unit price of £50, a Tier 3 of 8,000 units at 5% gives (0.05 − 0.015) × £50 × 8,000 = £14,000 per customer who gets there. The supplier sets aside £90,000 for Tier 3 true-ups, which pays for six of them before the budget breaks.
Which gives us the rule the whole algorithm is built to answer:
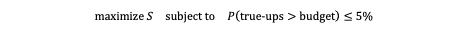
Where S is a score for how many valuable customers reach the top tier, which we define in the next section. Note this is a constrained optimization, not a single estimate, so the algorithm comes in two parts: a quantum circuit that scores one candidate program, and a search across candidate programs sitting on top of it. With only four candidates here, that search is a loop.
2. Encoding a rebate outcome as a Bernoulli random variable, and applying it to a qubit
This is where the coin from earlier earns its keep. We follow the quantum credit risk model, which gives every borrower one qubit that measures 1 if they default. Swap borrower for customer and default for “reaches Tier 3” and the structure carries straight across.
Eight customers, grouped by lifetime value:
| Customer | LTV group | Typical annual units μi | LTV weight wi | Volume uplift per 1% of rate |
| L1, L2, L3 | Low | 5,000 / 5,500 / 6,000 | 1 | +3% |
| M1, M2, M3 | Mid | 7,000 / 7,500 / 8,000 | 2 | +5% |
| H1, H2 | High | 10,000 / 11,000 | 4 | +7% |
Each customer’s annual volume follows their own bell curve, and a more generous top-tier rate is an incentive that shifts that curve upwards:

The Bernoulli variable is not the rebate program itself, it is a single yes or no outcome for one customer: do they reach the top tier or not. That gives us the probability we load into their qubit, exactly as we did with the coin:
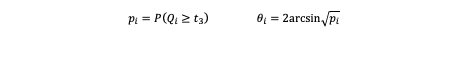
Eight customers, eight rotation angles, eight qubits. And “valuable customers” finally gets a definition, because the score we are maximizing is just the LTV-weighted share of customers expected to reach the top tier:
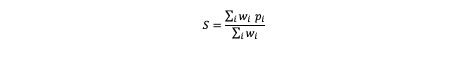
For the 8,000 units at 5% design, that works out at 72.8%. A high-value customer counts four times what a low-value one does, so the score rewards getting the right customers over the line rather than simply the most customers.
3. Deriving common demand drivers
If that were the whole model we would be done, and we would also be wrong. Treating eight customers as eight independent coins assumes their volumes have nothing to do with each other, and anyone who has watched a destocking cycle roll through a customer base knows better.
So we add one more ingredient, a shared demand driver written Z. It is worth being precise about what Z is, because it is easy to mistake for something it isn’t. It is a latent variable: an unobserved number standing in for whatever makes customers’ volumes land above or below forecast in the same year. It is not a market index, and customers do not “follow” it. It is simply a compact way of saying that volume surprises tend to move together. In B2B the usual suspects are:
- End demand in their industry, so distributors of building products all feel a slow construction season at once.
- Inventory cycles, with customers restocking or destocking at the same time.
- Our own actions. A list-price increase, a supply allocation or a longer lead time hits every customer simultaneously.
- Competitor moves, seasonality and weather.
Plenty of volume swings are still customer-specific, of course: winning a contract, opening a plant, changing a buyer. The model splits the two, so each customer’s outcome depends partly on the shared driver and partly on their own circumstances:

Φ is the standard normal distribution function, and ρ is the share of each customer’s volume surprise explained by the shared driver. At ρ = 0 the customers are fully independent and we are back to eight separate coins. Averaged across all values of Z each customer still reaches Tier 3 with probability pi, but given a particular Z their outcomes are linked.
ρ should be estimated rather than assumed: forecast each customer’s annual volume, take the gap between forecast and actual, then check whether those gaps move together across customers using a correlation or a principal component analysis. If a common component explains a meaningful share of the variation, set ρ to match it, and more often than not that component turns out to be something interpretable like an industry production index. If it explains very little, set ρ near zero and move on. The ρ = 0.3 used here is an illustrative assumption, not an estimate.
In the circuit, Z lives in two qubits holding four levels, running from a weak year for the shared driver to a strong one. And this is the bit that matters commercially: once customers share a driver, years where many of them reach the top tier at once become far more likely. The distribution of the total gets fatter tails, and budget breaches happen more often than an independent model would ever tell you.
4. Building the circuit that scores a design
Everything above now goes into a single circuit, which we will call A, running on 15 qubits:

Four steps, and each one is a gate we have already met:
- Load the demand driver. RY gates on the two factor qubits give each level of Z its probability.
- Load each customer, controlled on Z. For each level of Z, a controlled-RY sets customer i‘s qubit to reach Tier 3 with probability pi(z). This is the CNOT idea from the Bell state section, with a rotation in place of the flip.
- Count. Every customer who reaches Tier 3 adds 1 to a four-qubit count register.
- Compare with the budget. The budget pays for at most £90,000 / ΔR true-ups, so the objective qubit flips to 1 whenever the count comes in higher than that.
After A has run, that single objective qubit is a Bernoulli variable, exactly like the coin:
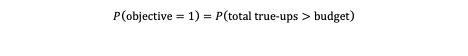
Which is the whole point of building it. Every customer, every level of the demand driver and every combination of outcomes, 28 × 4 = 1,024 scenarios in all, is held in one quantum state at the same time. We have not maximized anything yet. We have built the thing whose probability we are about to measure.
5. Estimating the risk using quantum amplitude estimation
The breach probability is now just the amplitude of that one objective qubit, which is precisely the quantity amplitude estimation was built to read. So we do exactly what we did with the coin, only with a much bigger circuit underneath it.
The Grover operator marks the outcome we care about by flipping the sign of the objective qubit, undoes A, reflects about the all-zeros state across all 15 qubits, and then redoes A. Undoing A is not as exotic as it sounds: it is the same gates in reverse order with the angles negated. Note what is being amplified here, because it is slightly counter-intuitive. Grover is amplifying the scenarios where the budget is breached, so that these rare and expensive years stand out well enough to be measured accurately.
We use the same maximum-likelihood estimation from earlier, running rounds of k = 0, 1, 2, 4, 8 and 16 Grover steps at 100 shots each, then picking the probability that best fits all six rounds together. Counting every use of the model, that is 6,800 runs.
For the Tier 3 design of 8,000 units at 5%, the exact answer is a breach probability of 8.32%. Amplitude estimation lands within about 0.1% of it. Plain sampling, given the same 6,800 model runs, has a typical error nearer ±0.3%. Same budget of work, roughly a third of the error, and the gap widens the more precision you ask for.
Worth walking through how that 8.32% is actually arrived at, since it is the number the whole design decision turns on.
Each Tier 3 crossing costs a £14,000 true-up, and the £90,000 budget covers six of them, so a breach means seven or eight of the eight customers crossing in the same year.
Now take each level of the demand driver in turn. At any given level of Z the customers are independent again, so working out the chance that seven or eight of them cross is straightforward arithmetic. Do that four times and weight the answers by how likely each level is:
| Demand driver Z | Average chance a customer crosses | How likely this sort of year is | P(7 or 8 cross) |
| −1.5, a weak year | 36% | 13% | 0.01% |
| −0.5 | 50% | 37% | 0.46% |
| +0.5 | 65% | 37% | 8.00% |
| +1.5, a strong year | 78% | 13% | 38.9% |
| Weighted average | 8.32% |
That is the whole calculation, and the bottom row is where the risk hides. A strong year carries a 39% chance of breaking the budget. It only turns up about one year in seven, but that is more than enough to drag the average up to 8.3%. Treating the customers as independent averages across customers and gets 3.1%. The linked model averages across types of year, and the one bad year dominates.
Two notes on provenance. This is a classical calculation rather than the circuit’s output, so amplitude estimation is being checked against it rather than producing it. And the four levels are weighted by the normal density, which matters because weighting them by the probability mass of the interval each one represents instead gives 9.06%.
6. Choosing the rebate program and measuring
Run that for all four candidate designs and the answer falls out:
| Tier 3 design | LTV score S | True-up ΔR | P(breach) if independent | P(breach), linked |
| 8,000 units at 3% | 65.8% | £6,000 | 0.00% | 0.00% |
| 8,000 units at 5% | 72.8% | £14,000 | 3.10% | 8.32% |
| 12,000 units at 3% | 30.6% | £9,000 | 0.00% | 0.00% |
| 12,000 units at 5% | 39.6% | £21,000 | 0.21% | 1.06% |
At a 3% top-tier rate the true-up is small enough that the budget covers all eight customers reaching Tier 3, so a breach is simply impossible. The interesting row is the second one.
The generous design, 8,000 units at 5%, has far and away the best LTV score at 72.8%. Treat the customers as independent and its breach risk is 3.1%, comfortably inside the 5% limit, and you would sign it off. Link the customers through a shared demand driver and that risk rises to 8.3%, well outside the limit. The best design that actually passes is Tier 3 at 8,000 units and 3%: a top tier that is still reachable, at a rate the budget can survive in a strong year.
Which is the commercial point, and it is one I would make even to someone who never wants to hear the word qubit again. The risk in a retroactive program is not the average true-up, it is correlated true-ups. A strong year for a shared driver pushes many customers over the cliff at the same time. Averages hide it, independent models hide it, and the linked model makes it visible. How big the effect is depends entirely on ρ, which is why it needs calibrating against your own portfolio before anyone chooses a design.
The one-factor model here can also be solved classically, and the exact check in my notebook does it in milliseconds, because fixing Z makes the customers independent again. The credit risk papers use a one-factor model for exactly that reason: it is a proof of concept whose answer you can verify. A real quantum advantage needs dependence that classical shortcuts cannot unpick, such as many interacting drivers, the timing of quarterly true-ups, or linked thresholds across products, where classical methods fall back on Monte Carlo and amplitude estimation beats it quadratically. And the hardware does not exist yet. Deep Grover sequences across hundreds of qubits need fault-tolerant machines, and everything here runs on a simulator with no real-world speed-up.
Conclusion
The purpose of this write up is to 1) give a clear understanding of core concepts of quantum computing for pricing and commercial scientists and 2) show an example of how a quantum rebate algorithm can theoretically be constructed. We’ve shown how to define an algorithm that given the right hardware, will define the best tier 3 rebate threshold and rate for a rebate based on:
- How likely each customer is to reach the threshold, allowing for the fact that a more generous rate shifts their volume upwards in the first place.
- How valuable each of those customers is, so that the right customers crossing counts for more than the most customers crossing.
- The size of the retroactive true-up that each crossing triggers.
- The budget set aside to pay for those true-ups.
- How closely customers’ volumes move together, because it is correlated crossings rather than average ones that break a budget.
- The chance of breaching that budget the business is actually willing to live with.
Using the right hardware (for example a fault-tolerant machine similar to IBM Quantum Starling due in 2029, which is designed for 100 million gates across 200 error-corrected qubits), and given:
- A problem classical shortcuts cannot unpick. The single shared driver used here collapses to an exact classical calculation in milliseconds. Real advantage needs several interacting drivers, true-ups landing quarterly rather than annually, or thresholds linked across products, where classical methods have to fall back on sampling.
- Scale. Thousands of customers across several products, not eight, so that pinning down a small tail probability genuinely costs a classical machine something.
- An efficient way to load the model. Preparing the circuit has to cost less than the sampling it replaces, otherwise the loading eats the advantage before the estimation starts. This is the part most quantum finance work gets stuck on.
- Fault-tolerant hardware. Hundreds of logical qubits, and therefore many more physical ones, able to hold a Grover sequence deep enough to finish without the errors swamping the answer.
- An honest classical baseline. Benchmarked against good Monte Carlo with variance reduction, not against a naive implementation chosen because it loses.
This theoretical approach has a credible route to outperforming non quantum computing methods for rebate definition. None of those conditions hold today, which is exactly why this is theoretical rather than a product.
I’ve really enjoyed my journey into the wacky world of quantum algorithm. Vendavo is committed to being at the forefront of innovation in the world of B2B commercial optimization. As far as I’m aware, this is the first application of a quantum approach to retroactive rebate program design, and I hope it spurs more ideas in the area of B2B commercial optimization.
Potential future work
Plenty left to do, and most of it is unglamorous.
- Constructing Z. Here it is an assumption rather than a measurement. Calibrate ρ from the gaps between forecast and actual volume, checking whether those gaps move together across customers. Then extend it to several factors, because a portfolio spread across industries needs more than one.
- Test on quantum hardware compared to classical monte carlo methods. With the honest version of the comparison, which means benchmarking against good classical Monte Carlo with variance reduction rather than a naive implementation that was always going to lose. Worth running first on a simulator with a realistic noise model, because that tells you what the hardware will do before you queue for it.
- Searching across many designs instead of four. Four candidates is a loop. A realistic program has many thresholds, rates and tier counts to choose between, and at that point the outer search becomes the interesting problem in its own right, as a Grover search or a QAOA over the design space rather than a for-loop over a handful of options.
- Finding the dependence that classical shortcuts cannot unpick. The honest weakness of this model is that a single shared driver can be solved exactly on a laptop. The versions that cannot are the ones worth chasing: several interacting drivers, thresholds linked across a product portfolio, or customers who respond to each other’s pricing. Those are also, conveniently, the versions that look most like a real rebate program.
Reach out to Vendavo to speak with an expert.